Votre panier est vide!
LIVRAISON GRATUITE PARTOUT | 30% De Réduction Sur Tout Le Site !


LIVRAISON GRATUITE PARTOUT | 30% De Réduction Sur Tout Le Site !

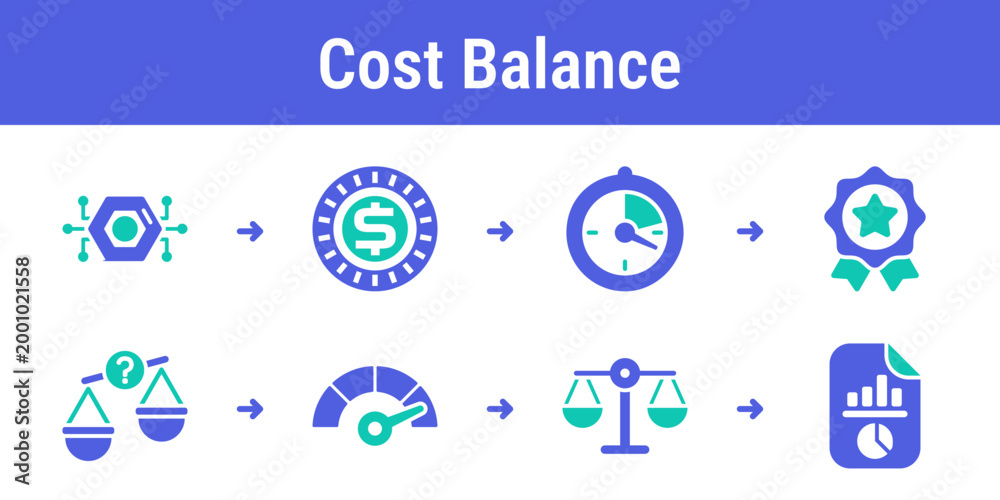
Practical sequence for balancing token count speed and response quality before releasing an optimized prompt Suitable for AI products cost analytics and model tuning dashboards
Code produit:
2001021558
La ou les dimensions que vous avez saisies sont inférieures à 24 ".
Êtes-vous sûr d'avoir saisi les mesures correctes?
Taille maximale
Vous n'avez pas entré les mesures correctes pour Canvas.


© Decomurale 2026 Tous droits réservés | Kanguru Digital Agency

